Which PC for LFM3? Memory, machine, level and license
Updated: November 15, 2026
Which PC for LFM3?
Even our smallest AI PC is more than enough, with plenty of headroom to spare.
LFM3, by Liquid AI, is a sub-2 billion parameter model. In 4-bit mode, it requires approximately 3 GB of GPU memory. All of our AI machines can run it, starting with the CoreIA RTX 5060 Ti. Its Omni version also supports images, video, and voice, and can respond via voice output.
Liquid AI released the LFM3 family on Hugging Face in late October 2026: LFM3-1.7B on October 23 for text, and LFM3-Omni-2B on October 21 for text, image, video, and audio. Liquid AI designed these for local agents, tool calling, and specialized applications. Here is what you need to run them locally, and what the published scores actually mean.
Two models, two use cases
| Model | Includes | Responds | Context |
|---|---|---|---|
| LFM3-1.7B | Text | Text, with reasoning | 256,000 tokens |
| LFM3-Omni-2B | Text, images, video with sound, audio | Text or voice | 32,000 tokens |
LFM3-1.7B is designed for agents: calling tools, filling specific formats, and executing simple tasks. LFM3-Omni-2B replaces voice transcription, image reading, dialogue, and speech synthesis in a single model. It does not reason; it provides direct responses.
Required memory
| Weight precision | LFM3-1.7B | LFM3-Omni-2B |
|---|---|---|
| Q4 (4 bits) | 2.9 GB | 3.1 GB |
| Q8 (8 bits) | 3.6 GB | 4.0 GB |
| FP16 (16 bits) | 5.1 GB | 5.9 GB |
Radiance Systems estimates based on 32,768 context tokens plus an operating margin, not measured on our machines. Even with the 256,000 tokens of LFM3-1.7B, our calculation remains around 5.5 GB in 4-bit, as only 6 of its 24 layers retain the full context.
Which machine
| Machine | GPU Memory | Price excl. VAT | LFM3 |
|---|---|---|---|
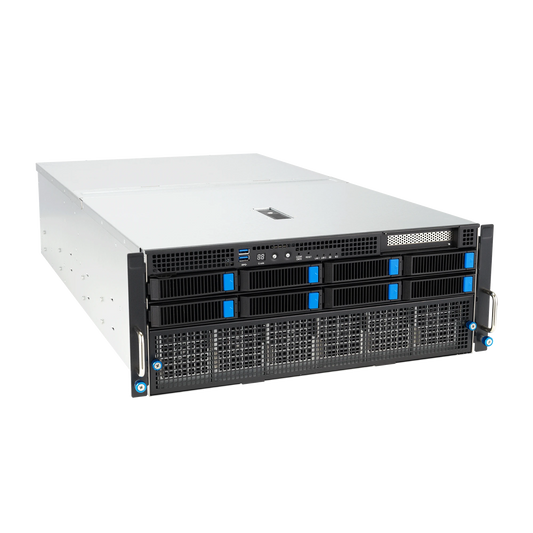
| CoreIA RTX 5060 Ti | 16 GB | €1,724 | Yes, in 4, 8, or 16-bit, with enough headroom for multiple agents |
| CoreIA RTX 5090 | 32 GB | €9,403 | Yes, with enough space to run a second, larger model simultaneously |
For LFM3 alone, the CoreIA RTX 5060 Ti is more than sufficient. A larger machine is only justified if you want to run LFM3 alongside a more powerful model, for example, using LFM3 for quick tasks and a 20 to 30 billion parameter model for complex queries.

View the CoreIA RTX 5060 Ti
Is it better than Gemma 4 12B?
Not according to the published figures. The LFM3-1.7B spec sheet compares it to Gemma 4 E4B, the smaller version of Gemma 4, which it outperforms in almost every test. It does not compare it to Gemma 4 12B. When comparing the two spec sheets, LFM3-1.7B falls significantly short of Gemma 4 12B in general knowledge (GPQA Diamond: 63.4 vs 78.8) and is at a similar level in coding (LiveCodeBench v6: 73.5 vs 72.0). These two spec sheets were not measured with the same settings: they are on different scales.
Its true strength lies elsewhere: for its size, it excels in agent tasks, tool calling, and following instructions, while hallucinating very little.
| Test (scores published by Liquid AI) | LFM3 1.7B | Gemma 4 E4B | Qwen3.5 4B | Qwen3.5 9B |
|---|---|---|---|---|
| WebArena-Verified (web agent) | 38.4 | 17.1 | 21.9 | 28.9 |
| BFCL V4 (tool calling) | 71.4 | 48.3 | 55.1 | 62.8 |
| IFEval (instruction following) | 96.7 | 90.0 | 92.5 | 92.1 |
| Non-hallucinated responses (AA-Omniscience) | 92.9 | 72.1 | 13.6 | 52.6 |
| GPQA Diamond (knowledge) | 63.4 | 57.9 | 75.8 | 80.4 |
| Average of all tests on the sheet | 49.4 | 31.7 | 39.3 | 47.2 |
Scores provided by Liquid AI, measured using their own settings: these represent an order of magnitude, not an independent ranking. "Answers without hallucination" refers to the non-hallucination rate of AA-Omniscience (public part).
Licensing for corporate use
Free for companies under $10 million in revenue
The LFM Open License v1.0 allows free commercial use as long as your company generates less than $10 million in annual revenue.
Above this threshold, an agreement with Liquid AI is required
Companies exceeding this threshold are not covered by this license for commercial use. Non-profit organizations remain covered for research and non-commercial use.
Required notices
In the event of redistribution, you must retain the license, the original notices, and identify any modified files.
Summary of the license text published with the model, which remains the only authoritative source. This does not constitute legal advice.
Is this model sufficient or do you need a larger one?
LFM3 is an excellent choice for fast, cost-effective agents: sorting emails, extracting data from documents, calling the right tools, and answering questions based on your files. For complex queries, advanced writing, or coding, a larger model remains preferable. Both can run on the same machine.
Which model fits your needs?
Tell us what you want to automate. We will advise you if LFM3 is sufficient or if a larger model is required, and specify which machine you need. Free, no-obligation quote.
FAQ
How much GPU memory is required for LFM3?
Approximately 3 GB in 4-bit, 4 GB in 8-bit, and 5 to 6 GB in 16-bit, with a 32,768 token context window. These are Radiance Systems estimates.
What is the smallest PC to run it?
Our CoreIA RTX 5060 Ti, featuring 16 GB of GPU memory, runs it in 4, 8, or 16-bit while leaving plenty of room for multiple agents.
Is LFM3 better than Gemma 4 12B?
According to the published figures, it outperforms Gemma 4 E4B (the smaller version of Gemma 4) but falls short of Gemma 4 12B in general knowledge, while performing at the same level in coding. Its main strengths lie in agentic workflows and tool calling.
What is the difference between LFM3-1.7B and LFM3-Omni-2B?
LFM3-1.7B processes text only, with a 256,000 token context window. LFM3-Omni-2B supports images, video, and audio, and can provide voice responses, with a 32,000 token context window.
Can it be used in a corporate environment?
Yes, it is free if your company generates less than $10 million in annual revenue. Beyond that, a license agreement with Liquid AI is required.
Which software should I use?
Liquid AI recommends vLLM, SGLang, and Transformers on a graphics card, or llama.cpp, Ollama, or LM Studio using GGUF files.
What speed can I expect?
We have not tested LFM3 on our machines and therefore cannot provide specific speed benchmarks.
Sources: Liquid AI, LFM3-1.7B spec sheet ; Liquid AI, LFM3-Omni-2B spec sheet ; LFM Open License v1.0 ; Google, Gemma 4 12B spec sheet. Data as of November 15, 2026.