Local AI PC 2026: what hardware to run a LLM locally?
In 2026, running AI locally is no longer just for data centers or engineers. Open-source models have exploded in quality — Llama 4, Qwen 3.5, DeepSeek V4, Gemma 4, Mistral Large 3 now rival the best proprietary models — and consumer hardware allows full utilization. This guide explains how to choose your local AI PC based on your usage and budget.
Why Local AI is Essential in 2026?
1. Confidentiality and GDPR — an Obligation for Regulated Professions
A local AI workstation solves this problem by design. Data never leaves your network. GDPR compliance is natively guaranteed, professional secrecy is respected, and there's zero transfer outside the EU.
2. Zero Recurring Cost
A ChatGPT Pro subscription costs €20/month/user — €240/year. For a team of 5 people, that's €1,200/year in pure expenditure, with the added concern of your data on third-party servers. A local AI workstation pays for itself in 12 to 24 months, then produces without additional cost for years.
3. Open-source Models Have Reached Frontier Level in 2026
The Best Open-Source LLM Models for Local Use — May 2026
| Model | Size / Architecture | VRAM (Q4) | Strengths | Ideal for |
|---|---|---|---|---|
| Llama 4 Scout 17B | 17B MoE · Meta | ~10-12 GB | Best quality/VRAM ratio 2026, 10M context | General use, 12 GB VRAM |
| Gemma 4 26B QAT | 26B dense · Google | ~14 GB | 85 tok/s on consumer GPU, 256K context, multimodal | Speed + quality, long summaries |
| Qwen 3.5 14B / 32B ⭐ | MoE · Alibaba | ~10 GB (14B) / ~20 GB (32B) | Multilingualism, multimodal, 8.6× better throughput vs Qwen3 | French, multilingual, versatile |
| DeepSeek V4 Flash | 284B total / 13B active | ~10-12 GB | Advanced reasoning, code, agentic, MIT | Accounting, code, analysis |
| Mistral Medium 3.5 | MoE · Mistral AI | ~16 GB | 77.6% SWE-Bench, EU-friendly, excellent in French | Law, writing, European firms |
| DeepSeek R2 8B | 8B dense · MIT | ~5 GB | Best math/logic reasoning in 8B, lightweight | Modest machines, quick analysis |
| Kimi K2.6 | 1T MoE / variable active | Multi-GPU | #1 open source coding (Quality Index 53.9) | Dev teams, AI servers |
| DeepSeek V4 Pro | 1.6T total / 49B active | Multi-GPU | 90.1% GPQA Diamond, 1M context, GPT-5-mini level | Enterprise AI servers |
Sources: CoderSera (May 2026), BentoML (May 2026), PromptQuorum (May 2026), WhatLLM.org (April 2026). Updated May 13, 2026.
How to Choose Your Local AI PC: VRAM Above All Else
The number one criterion for local LLM inference is GPU memory (VRAM). Inference is limited by memory bandwidth — the GPU continuously loads model weights from VRAM. More VRAM = larger models = better responses.
| Available VRAM | Compatible Models (Q4) | Examples May 2026 | Approx. Speed |
|---|---|---|---|
| 5-8 GB | Up to 9B | DeepSeek R2 8B, Qwen3 8B, Gemma 3 4B | 50–90 tok/s |
| 12 GB | Up to 17B MoE | Llama 4 Scout 17B, Gemma 3 12B | 30–50 tok/s |
| 16 GB ⭐ Sweet spot | Up to 14B dense / 17B MoE | Qwen 3.5 14B, Mistral Medium 3.5, Llama 4 Scout | 40–70 tok/s |
| 24 GB | Up to 27-32B | Qwen 3.5 32B, Gemma 4 26B | 25–45 tok/s |
| 32 GB (RTX 5090) | Up to 70B in Q4 | Llama 4 Maverick Q4, Qwen 3.5 72B Q4 | 15–30 tok/s |
| 128 GB unified (GB10) | Up to 200B+ in Q4 | DeepSeek V4 Flash FP16, Llama 4 Maverick FP16 | 20–40 tok/s |
| 64–192 GB (multi-GPU) | 70B FP16 to 500B+ MoE | DeepSeek V4 Pro, Kimi K2.6, GLM-5.1 | Variable |
Our Local AI Workstations — Configured, Tested, Delivered Ready to Use
Radiance Systems designs local AI workstations for professionals who cannot entrust their data to a remote server. Each machine is hand-assembled in Auriol (13390), Provence, and delivered throughout Europe.

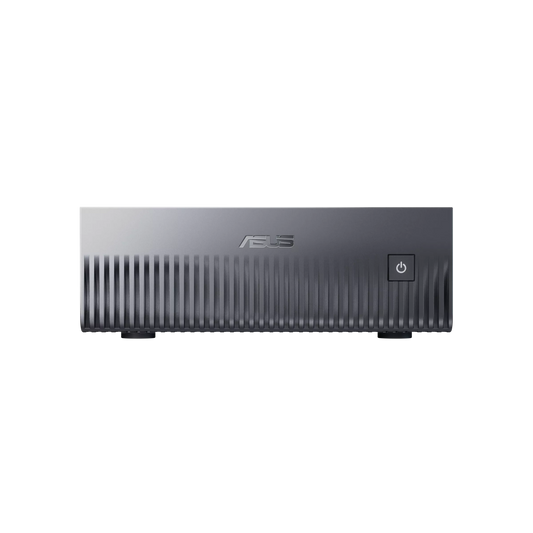
NVIDIA GB10 Mini AI Server — ASUS Ascent GX10
✅ Llama 4 Maverick FP16 · DeepSeek V4 Flash FP16 · Up to 200B parameters
128 GB of unified memory allows loading models that even an RTX 5090 (32 GB) cannot hold. 15×15 cm form factor, silent, consumes a standard outlet. CPU+GPU architecture fused on a single chip with NVLink-C2C at 900 GB/s.
Delivered ready to use · Ollama pre-installable on request
Configure this server →
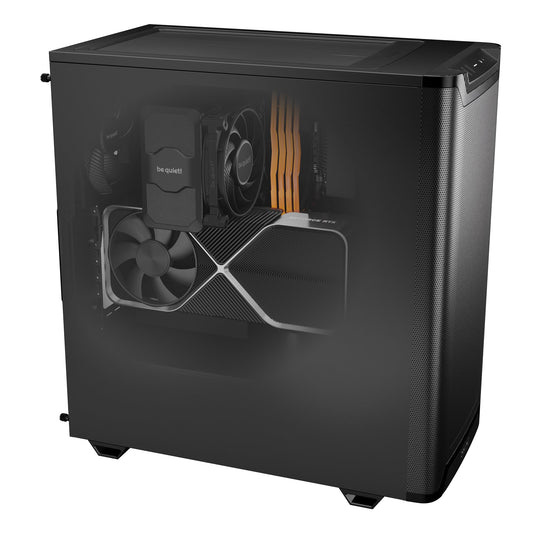
Radiance PC CoreAI 16 — RTX 5060 Ti 16 GB
✅ Qwen 3.5 14B · Mistral Medium 3.5 · Llama 4 Scout 17B · 40-70 tok/s
The 2026 sweet spot for professional local AI. 16 GB GDDR7 for 14-17B models entirely on GPU. AM5 DDR5 platform, compact and silent case. Ideal entry point for an individual practice.
Fully configurable · Case, RAM, SSD of choice
Configure this workstation →
Radiance PC CoreAI 32 — RTX 5070 Ti 16 GB
✅ Gemma 4 26B · Qwen 3.5 32B · DeepSeek V4 Flash · 25-45 tok/s
The versatile workstation for demanding liberal professions. Significantly higher memory bandwidth for 26-32B models. Ryzen 9 9900X for mixed CPU loads (RAG, document processing, n8n).
Fully configurable · Cooling, GPU, storage of choice
Configure this workstation →
Radiance PC CoreAI 64 — RTX 5090 32 GB
✅ Llama 4 Maverick Q4 · Qwen 3.5 72B Q4 · DeepSeek V4 Flash Q4 · 15-30 tok/s
The best consumer GPU for LLM inference in 2026. 1,792 GB/s bandwidth, market-leading for consumers. 70B models in Q4 entirely on GPU. Light fine-tuning possible. Ryzen 9 9950X3D for intensive RAG pipelines.
Fully configurable · Fine-tuning possible
Configure this workstation →
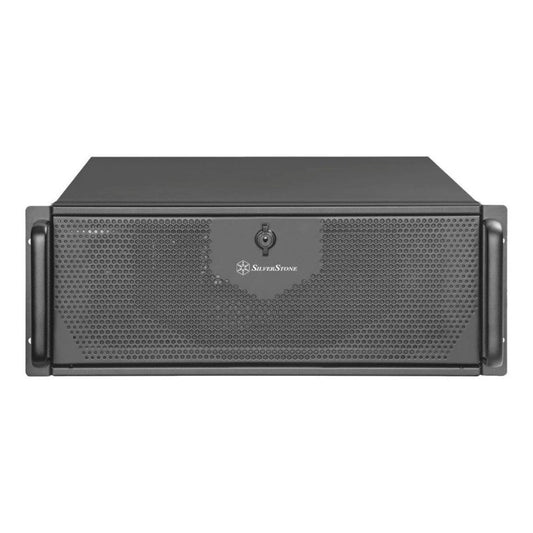
Radiance CoreAI Rack — 2× RTX 5090 (64 GB VRAM)
✅ DeepSeek V4 Flash FP16 · Llama 4 Maverick FP16 · Simultaneous multi-GPU inference
64 GB of total VRAM for teams of 5 to 20 users sharing an internal AI server. Simultaneous inference on two independent GPUs. Ideal for practices with multiple collaborators.
Custom-made · 4U Rack · Quote on request
Configure this rack →
CoreAI 128 Rack — 2× RTX 6000 PRO Blackwell (192 GB ECC)
✅ Kimi K2.6 · DeepSeek V4 Pro Q4 · Fine-tuning 70B+ · GPU Virtualization
Professional GPUs with ECC memory for continuous production. 192 GB of ECC VRAM allows loading the largest open-source models — Kimi K2.6, DeepSeek V4 Pro — in native or high-quality precision. Maximum reliability for critical environments.
Custom-made · 4U Rack · On-site installation possible
Configure this rack →
Radiance PC Pro AI Ultra Threadripper
✅ Fine-tuning · Distributed Training · Massive RAG Pipelines · HPC · Simulation
The ultimate workstation for demanding production environments. Threadripper PRO sTR5 platform expandable up to 96 cores and 2TB ECC RDIMM RAM. For mixed workloads: AI, 3D rendering, simulation, HPC. The most scalable solution in the catalog.
Custom-made · Personalized quote · On-site installation
Request a quote →Which local AI PC for your profile?
| Profile | Recommended configuration | Target LLM models (May 2026) | Budget |
|---|---|---|---|
| Individual liberal professional | CoreAI 16 RTX 5060 Ti 16 GB | Qwen 3.5 14B, Mistral Medium 3.5, Llama 4 Scout | ~€1,700 |
| Compact individual practice ⭐ | ASUS Ascent GX10 (GB10) | Up to 200B · DeepSeek V4 Flash FP16 | ~€4,000 |
| Mixed AI + intensive office use | CoreAI 32 RTX 5070 Ti | Gemma 4 26B, Qwen 3.5 32B | ~€2,400 |
| 70B models, light fine-tuning | CoreAI 64 RTX 5090 | Llama 4 Maverick Q4, DeepSeek V4 Flash Q4 | ~€6,000 |
| Team of 5-20 people, internal AI server | Rack 2× RTX 5090 | DeepSeek V4 Flash FP16, simultaneous inference | ~€11,000 |
| Continuous production, 70B+ fine-tuning | Rack 2× RTX 6000 ECC | Kimi K2.6, DeepSeek V4 Pro | ~€28,000 |
| HPC AI / R&D Infrastructure | Pro AI Ultra Threadripper | All models, distributed training | ~€20,000+ |
Local AI for your business
Lawyers & Notaries
Analyze files and contracts, summarize in natural language, identify risky clauses — without exposing your clients. RAG on your internal document base.
Doctors & Clinics
Dictated reports, analyzed patient histories, queried medical database — without a single byte leaving your network.
Accountants & Auditors
Analyze balance sheets, detect anomalies, generate reports — without ever uploading your clients' confidential figures.
Design Offices & R&D
Leverage AI for your research and simulations without exposing patents, formulas, or project data to third-party services.
SMEs & General Management
AI assistant connected to your internal documents, procedures, and CRM — for all your teams, on your network, without external access.
Developers & Tech Teams
Code assistance (Kimi K2.6, Qwen 3.5 Coder), debugging, refactoring — entirely local with your proprietary codebase.
Frequently Asked Questions — Local AI PC 2026
What is the best local LLM model in May 2026?
It depends on the use case. Llama 4 Scout 17B offers the best quality/VRAM ratio (12 GB) for general use. Qwen 3.5 14B excels in multilingualism and French. DeepSeek V4 Flash is best for reasoning and code. Gemma 4 26B QAT is the fastest (85 tok/s on consumer GPUs). For servers with more VRAM, DeepSeek V4 Pro and Kimi K2.6 reach the level of the best proprietary models.
Does a local LLM compete with ChatGPT in 2026?
For almost all daily professional tasks, yes. DeepSeek V4 Pro achieves 90.1% on GPQA Diamond — on par with GPT-5-mini. Mistral Medium 3.5 achieves 77.6% on SWE-Bench Verified for code. The remaining gap is in very complex reasoning tasks and advanced multimodality. For legal, medical, and accounting uses, a good local model is largely sufficient.
Do you need technical knowledge to use a local LLM?
No. Our workstations come with Ollama and Open WebUI pre-installed on request — an intuitive web interface similar to ChatGPT, which runs entirely locally from a browser. No command line necessary for daily use.
Can you connect your documents to a local LLM (RAG)?
Yes. Open WebUI natively integrates document RAG — upload your PDFs, Word, or Excel files and query them directly in natural language. For more advanced pipelines, n8n can orchestrate complete workflows between your files, your local LLM, and your business applications.
Do you deliver outside of France?
Yes, Radiance Systems delivers throughout the European Union. On-site installation is possible in France and neighboring countries. Remote installation is also available via SSH or TeamViewer.